엔비디아가 추론 칩 '그록 3 LPX(Groq 3 LPX)'를 완전 양산 단계로 전환하며 젬마4 31B 모델에서 초당 3400 토큰을 처리해 세레브라스보다 4배 빠르다고 발표했다. 다만 더 레지스터에 따르면 엔비디아는 이 성능을 내기 위해 최소 64개의 가속기가 필요한 반면 세레브라스는 1~2개만으로 충분해 단순 비교에는 한계가 있으며, 대형 MoE 모델에서의 확장성은 여전히 미지수로 남아 있다.
- •엔비디아 그록 3 LPX, 젠마4 31B에서 초당 3400토큰…세레브라스 대비 4배
- •엔비디아는 64개 가속기 필요, 세레브라스는 1~2개로 충분해 단순비교엔 한계
- •대형 MoE 모델에서의 아키텍처 확장성은 아직 검증되지 않음
0단 자동
AI가 규칙대로 쓰고 그대로 게시했습니다. 사람이 따로 보지 않았습니다.
- 규칙 판
- 규칙 판 도입 이전 기사입니다.
- 남기는 것
- 규칙 판 · 모델 · 시각
- 판 기록
- 아직 없습니다.
Nvidia says its Groq 3 LPX is four times faster than Cerebras, but the math is more complicated
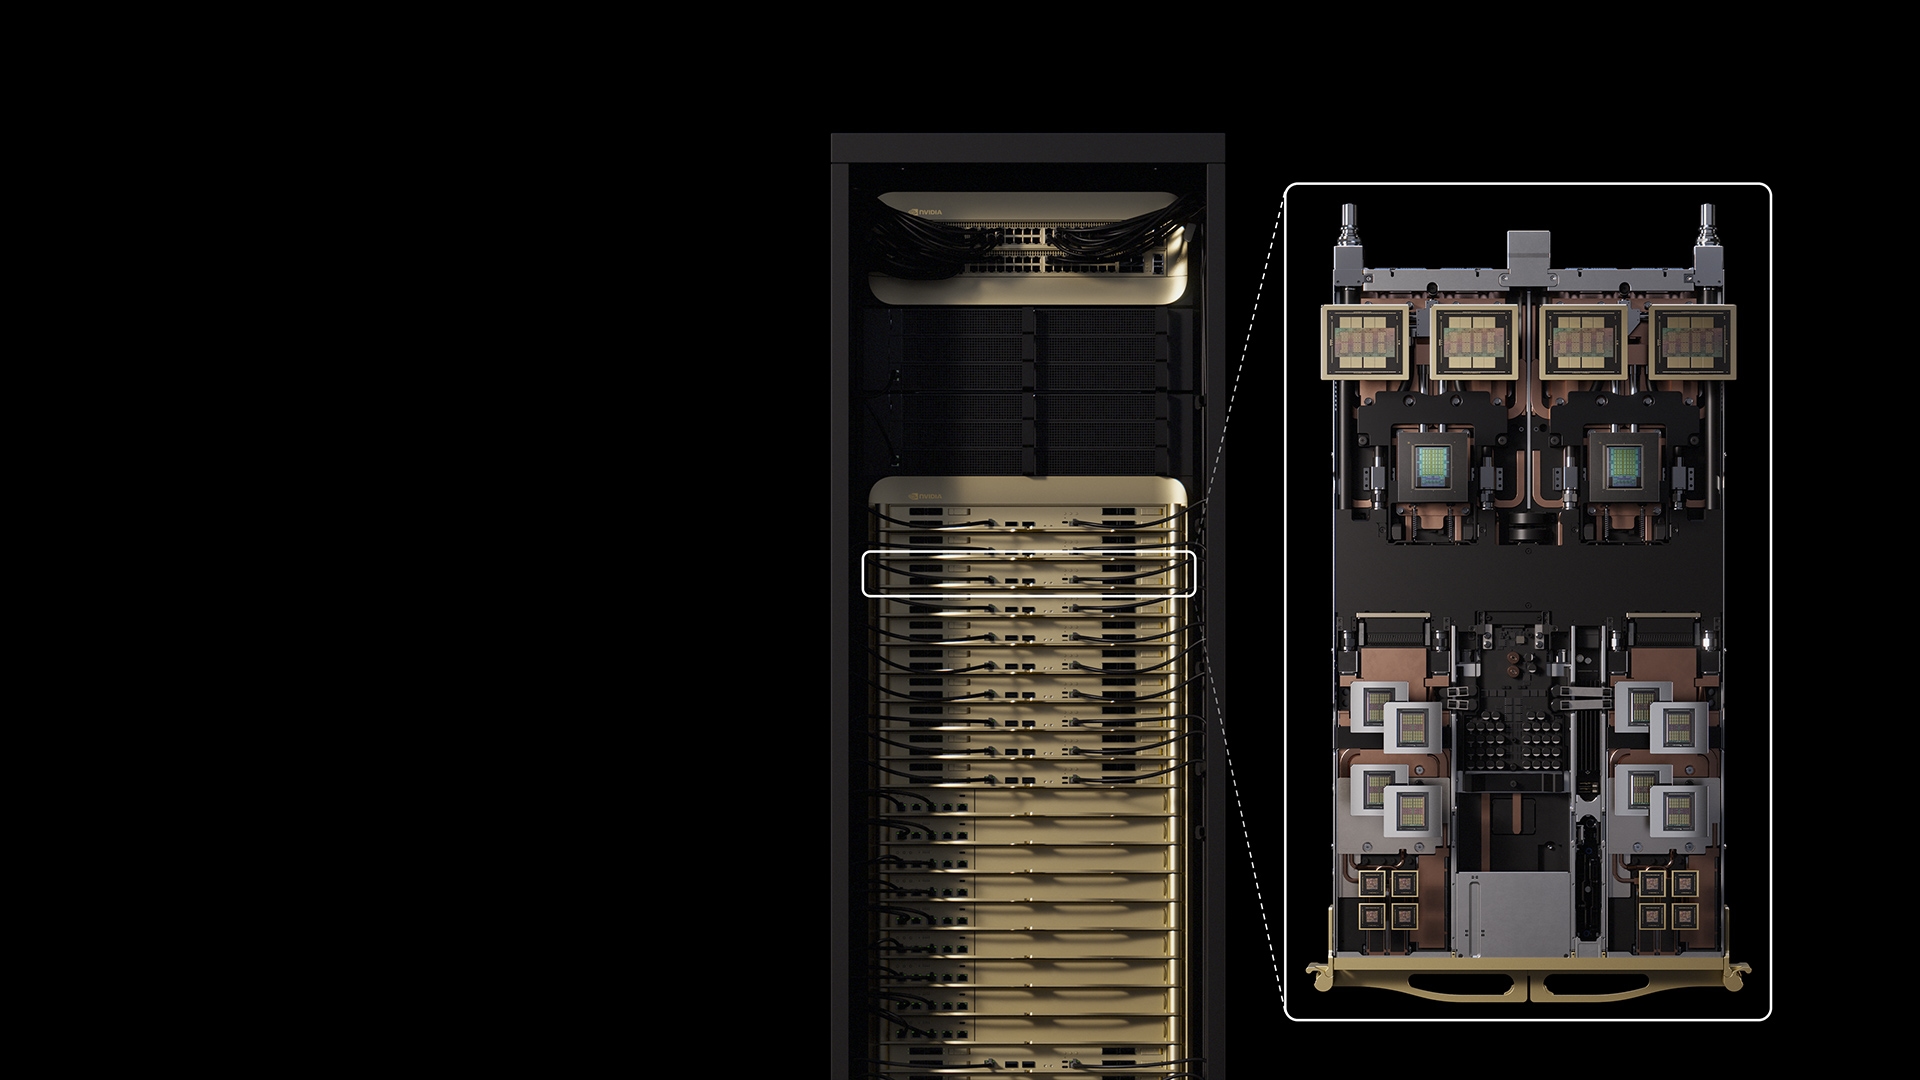
본문 미리보기
Nvidia is moving its Groq 3 LPX inference chip into full production and reports 3,400 tokens per second on Gemma 4 31B, four times faster than Cerebras. But the numbers don't tell the whole story. Nvidia needs at least 64 accelerators to get there, while Cerebras needs only one or two, according to The Register. How well the architecture scales with large MoE models remains an open question. The article Nvidia says its Groq 3 LPX is four times faster than Cerebras, but the math is more complicat
전체 내용이 궁금하다면?
원문을 직접 읽어보세요
이 글이 만들어진 과정
- 10:33AI 초안


